Riteng Zhang (Gavin)

About

I am currently a second-year PhD student in Purdue ECE, advised by Xiaoqian (Joy) Wang, working on LLM interpretability.

I earned B.A. degrees in Computer Science and Mathematics, with a minor in Philosophy, from Boston College. During my undergraduate studies, I was advised by Professors Emily Prud’hommeaux, Sergio Alvarez, Yuan Yuan, and Maira Marques Samary.

Email:

Interests

AI/ML research

  • Mechanistic interpretability
  • LLM interpretability
  • AI safety
  • Modular neural networks

Philosophy

  • Epistemology
  • Philosophy of science
  • Philosophy of religion
  • Pragmaticism

History

  • Chinese history
  • Roman history
  • Medieval history
  • Central and West Asian history

Awards & Achievements

  • John McCarthy, S.J., Award for Natural Science — Boston College, May 2024. Awarded annually to one student for the best senior thesis in Natural Science.
  • Neuhauser Award — Boston College Computer Science, May 2024. Awarded annually to 1–2 Computer Science students receiving exceptional recognition from faculty.
  • Scholar of the College — Boston College, May 2024. Awarded to exceptional students who completed substantial, high-quality independent work under faculty supervision.

Research Projects

Rethinking SAE Evaluation: An Atomic Interpretable Unit Framework Reveals Hidden Polysemanticity and Redundancy

accepted NeurIPS 2026 · Evaluations & Datasets Track

Riteng Zhang, Xiaoqian Wang

We evaluate sparse autoencoders as systems of atomic interpretable units, examining non-redundancy, completeness, monosemanticity, dead units, and sparsity. Our framework reveals a dominant-feature failure mode: highly influential features can remain polysemantic or redundant even when conventional evaluations appear favorable.
in review ICLR 2027
Title and details withheld during review.
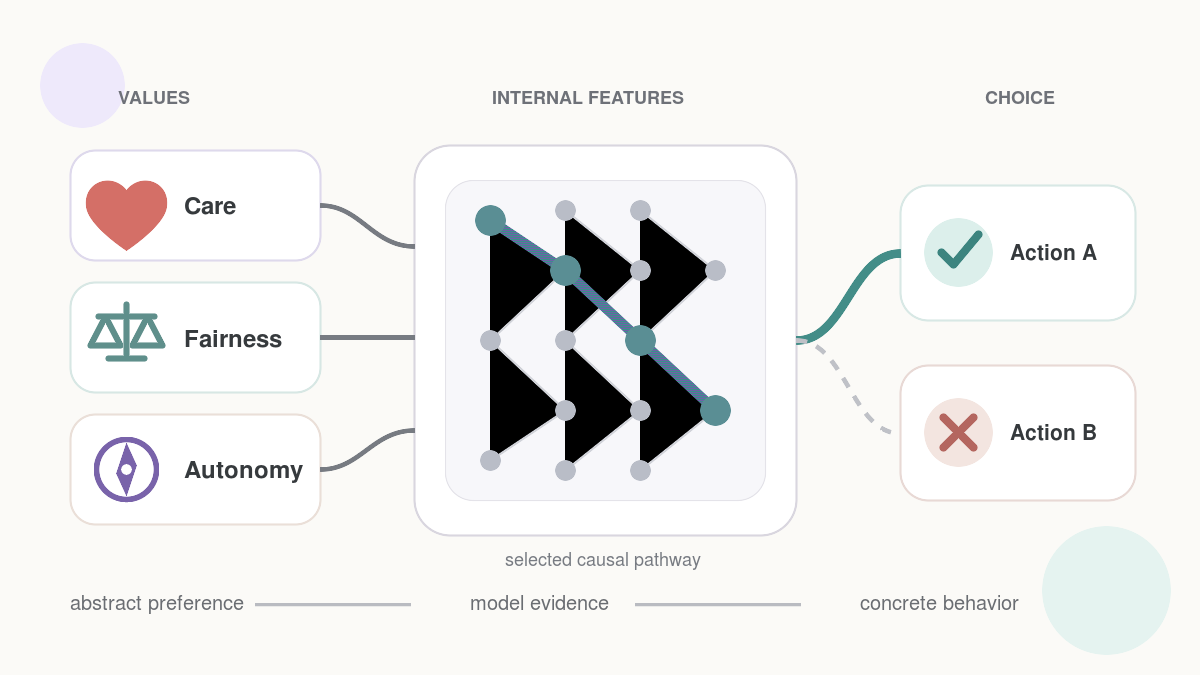
Values connected through internal model features to concrete action choices
How values may connect to internal features and concrete choices.

What Models Say vs. How They Act: Mechanistic Interpretability of Value–Action Gaps

ongoing research Mechanistic interpretability · language model behavior

We study how language models translate abstract value preferences into concrete choices. The project connects behavioral experiments with activation-level and causal evidence inside the model.
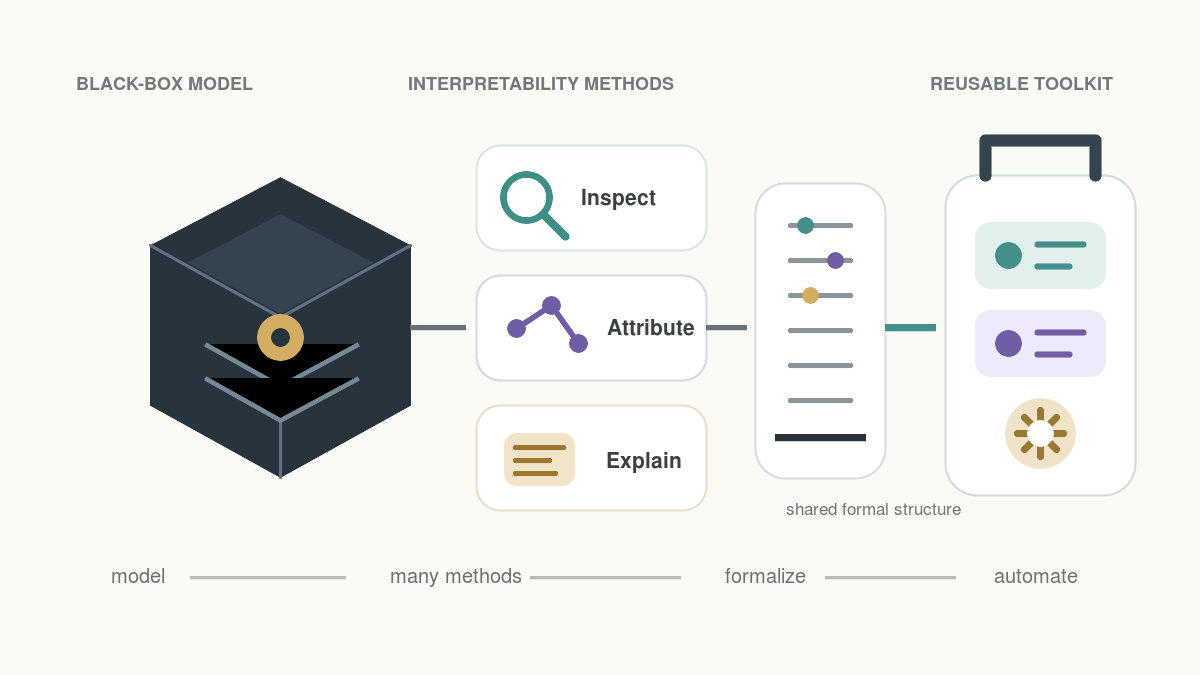
Interpretability methods becoming a formalized reusable toolkit
From individual interpretability methods to a reusable formal toolkit.

A Framework for Formalizing and Automating Interpretability

academic work Boston College senior thesis · 2024

My senior thesis introduced the Formalizing and Automating Interpretability Toolkit (FAI), a structured way to describe, compare, select, and implement interpretability methods.

Teaching

At Boston College, I served as a teaching assistant for two upper-level computer science courses. I supported Machine Learning for two semesters.

Boston College · Teaching Assistant

Machine Learning (CSCI3345.01)

Two semesters · 2023–2024

Graded assignments, held office hours, and designed selected homework and sample code across both semesters.

Boston College · Teaching Assistant

Vision and Learning (CSCI3399.01)

2023–2024

Graded assignments, held office hours, and organized student presentations.